

Free proxies are a poor fit for production scraping. In a 30-month study of 640,600 proxies from 11 providers, only 34.5% were reachable at least once, and 16,923 showed signs of content manipulation. Because a block page can arrive with an HTTP 200 status, treat any free proxy as untrusted infrastructure and validate the response body, not just the status code.
Free proxies are the wrong default for production web scraping, and the reason is narrower than most listicles admit: you cannot audit infrastructure you cannot identify.
A proxy does hide your scraper’s IP from the target site. What it hides from you is the operator’s logging, the provenance of the IP, and whether the bytes coming back were altered somewhere in the middle. Those are the three things that decide whether your dataset is worth anything six months from now.
The failure that hurts most is quiet. Your scraper gets 200 OK, parses a page, writes rows to the database — and the page was a challenge screen, a consent wall, or a copy of the real page with three affiliate links swapped out. No exception fires. No alert triggers. Three weeks later your price index is off by 4%, and nobody can point to the day it happened.
So the useful question is not “free or paid.” It is whether you can verify who runs the service, how it handles your traffic, what it logs, where its addresses come from, and whether the payload it hands you matches what the site actually served. Everything below is a concrete way that question gets answered badly. If you are new to the mechanics, start with what data scraping involves before you pick a network path — the data model determines how much proxy risk you can absorb.
Where Free Proxies Break Down: Ten Failure Modes
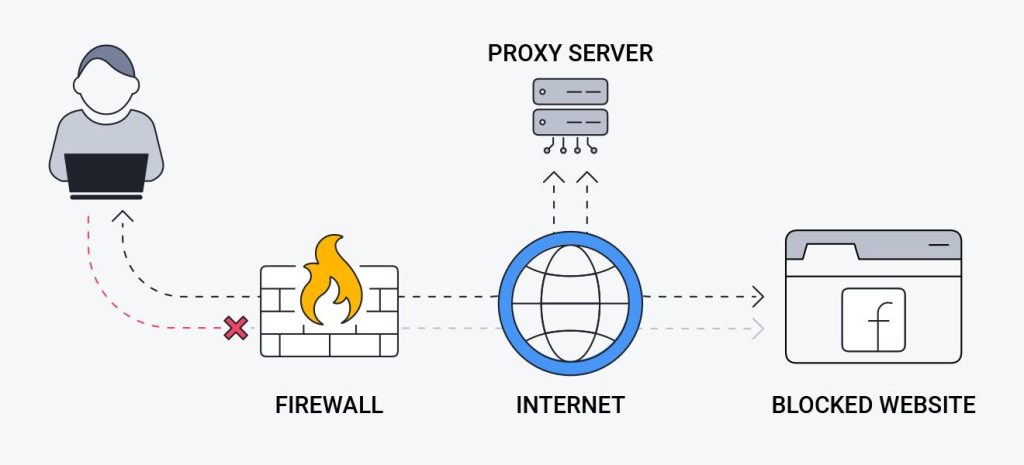
Free proxies fail in a predictable set of ways: opaque ownership, unencrypted transit, documented content manipulation, availability churn, latency swings, inherited IP reputation, false success signals, regional data drift, retry-driven duplicates, and stale responses. Each one becomes more expensive as your job grows from hundreds of requests to millions.
One failed request is a blip. Ten thousand inconsistent responses is a data quality incident, a debugging week, and often a rewrite of the validation layer you should have built first.
1. The Operator Becomes Part of Your Trust Chain
Every proxy puts a third party inside the request path between your scraper and the target. With a commercial provider, you can usually find a company registration, a data-retention policy, an abuse contact, and a status page. With an address taken off a public list, you have an IP, a port, and a country flag.
Openness itself is neutral. A proxy that accepts anonymous connections may log nothing at all; a paid endpoint with a beautiful dashboard may log full request bodies. Authentication tells you who gets in, not what happens to your traffic afterward. The gap that matters is that you cannot ask a public list those questions and get an answer.
That is why public proxies are a bad place to send anything sensitive:
- Login credentials or authorization headers
- API keys and access tokens
- Session cookies
- Personal or customer information
- Private URLs or unpublished endpoints
- Confidential search terms or business data
If your collection pipeline touches any of those, the relevant reading is API security practices for data collection platforms — the credential handling rules there apply whether or not a proxy sits in the path.
2. Unencrypted Traffic Is Readable and Editable
Plain HTTP leaves the payload visible at every hop, and a proxy is a hop. Whoever operates it can rewrite links, inject scripts, change a price, or redirect the request, and your scraper will parse the result without complaint.
HTTPS closes most of that gap, but only if your client validates the certificate chain. Inside a normal tunnel the proxy forwards ciphertext it cannot read, which is why HTTP, HTTPS, and SOCKS5 proxies behave so differently in practice — the protocol decides how much of your traffic the operator can even see. SOCKS5 in particular moves raw bytes at a lower layer, which changes what a scraping stack can do with it, but says nothing about the trustworthiness of the person running the server.
Never disable TLS certificate validation to make a free proxy work. A certificate warning is either a misconfiguration or an interception attempt, and silencing it removes the one check that would have told you which. The OWASP Transport Layer Security guidance covers correct certificate handling and what a broken chain actually indicates.
3. Content Manipulation Is Measured, Not Rumored
Yes, free proxies alter pages — and this has been quantified. A team from the University of Lille, CNRS, Inria, and Datadome ran a 30-month longitudinal study across more than 640,600 proxies collected from 11 providers and published the results at MADWeb 2024.
The headline numbers are bad enough. Only 34.5% of the collected proxies responded at least once during daily testing, and 16,923 proxies actively manipulated content. The numbers that rarely get quoted are worse: scanning the proxy IPs through Shodan surfaced 4,452 distinct vulnerabilities, including 1,755 that permit remote code execution and 2,036 that allow privilege escalation on the host device. Another 42,206 addresses appeared to run on MikroTik routers — consumer hardware conscripted into someone else’s proxy pool.
Read the methodology and its limits in A Vulnerability and Longitudinal Analysis of Free Proxy Services. The finding that should stay with you is not “free proxies are evil.” It is that a manipulated response is invisible to any scraper whose only health check is the status code.
4. Availability Churns Without Warning
Public proxies disappear. An address that answered during your Tuesday smoke test may be gone by the time the scheduled job runs at 3 a.m., and there is nobody to page.
You end up building a proxy health subsystem you never planned for: liveness probes, dead-address eviction, per-attempt failure logging, and a quarantine path so a half-read response never reaches the warehouse. That work has a real cost. Free infrastructure is not free; it trades a subscription line item for engineering hours and corrupted rows.
5. Latency and Throughput Swing Wildly
Response times on public proxies are erratic because the servers are oversubscribed, the bandwidth is thin, and the routing is whatever the host happens to have. The same address can answer in 200ms and then take nine seconds, or never.
This breaks timeout tuning. Set 5 seconds and you discard requests that would have completed; set 60 and your workers sit blocked on sockets that will never resolve. Raising concurrency makes it worse, because you are pushing more load onto a machine that was already struggling.
Measure both median and 95th-percentile latency, not the average. A proxy with a fine median and a catastrophic p95 will pass your smoke test and stall your nightly run.
6. Shared IPs Carry Reputation You Did Not Earn
Public proxy addresses are shared with strangers. Some of those strangers run spam, credential stuffing, scrapers far more aggressive than yours, or plain fraud. By the time you send your first perfectly reasonable request, the address may already be on the target’s blocklist.
What that looks like from your side:
- HTTP
403or429responses - CAPTCHAs and browser-verification interstitials
- Temporary or permanent IP blocks
- Redirects to login or consent pages
- Search results that differ from what a normal visitor sees
- Extra identity or location checks
The workload shape matters here too. A focused scraper and a crawler hit a site very differently — one walks a known list, the other keeps discovering URLs. Pair a broad crawler with a burnt IP range and the block rate climbs fast. If that is where your project is heading, read up on using proxies without getting blocked before you scale the job.
7. A 200 Response Does Not Mean the Scrape Worked
This is the expensive one. 200 OK tells you the server answered the request. It says nothing about whether the body contains the page you asked for.
A scraper that trusts the status code will happily ingest:
- A CAPTCHA or challenge page
- An access-denied message served with a success code
- A proxy-generated error page
- A login or cookie-consent screen
- A truncated document that closed mid-transfer
- Content for the wrong region
- A page with injected or substituted elements
Build the validation layer first. Here is a starting shape, in the style you would write it with Scrapy middleware or a plain requests wrapper — the logic is the same either way:
import hashlib

def validate(resp, expected_selectormarker, min_bytes=2000):
    if resp.status_code != 200:
        return False, "bad status"
    if "text/html" not in resp.headers.get("content-type", ""):
        return False, "wrong content type"
    if len(resp.content) < min_bytes:
        return False, "body too small"
    if expected_selectormarker not in resp.text:
        return False, "expected element missing"
    return True, hashlib.sha256(resp.content).hexdigest()
Store that hash alongside every row. When two proxies return different digests for the same URL within the same hour, you have found a manipulation candidate without writing a single string comparison by hand.
8. Proxy Location Silently Changes the Data
Websites localize by IP. Move the proxy country and prices, currency, language, stock status, search rankings, tax treatment, shipping estimates, and consent banners all shift with it.
That is useful when you want regional data on purpose. It is destructive when the exit location drifts and your schema never records it. Picture a price monitor pulling the same SKU through exits in the United States, Germany, and Singapore: three different numbers, all technically valid, all written to one column. Currency, VAT, and regional list pricing explain the spread, but nothing in the table says so.
Always persist the observed exit country, currency, language, timestamp, and target URL next to the payload. Read the location off the response, not off the provider’s dashboard — the two disagree more often than vendors like to admit.
9. Retries Can Manufacture Duplicate Records
Duplicates come from your pipeline, not from the proxy. URL parameters, pagination offsets, session state, and retry logic are the usual suspects.
Unreliable proxies turn a small bug into a large one. The target processes the request, the proxy drops the connection before the body reaches you, your scraper retries through a different exit, and now two rows describe one item. Without a stable natural key and a deduplication pass, both survive.
Fix it below the proxy layer: normalize URLs, assign a deterministic ID per record, log the outcome of every attempt, and deduplicate on write.
10. Stale Responses Usually Are Not the Proxy’s Fault
An intermediary can serve cached content, but a stale record is more often the target’s CDN, your own response cache, or a selector that quietly started matching an old template.
Diagnose instead of blaming. Log the Age, ETag, Last-Modified, and Cache-Control headers for anything where freshness matters, keep collection timestamps, use conditional requests where the site supports them, and diff against an independent source. If the timestamps say the response is fresh and the content says otherwise, the problem is upstream of the proxy.
Are Free Proxies Safe for Web Scraping?
No. Treat them as untrusted infrastructure — systems you did not choose, cannot inspect, and have no recourse against when they behave badly.
The same posture you would apply to any third party on the network applies here: assume no trust by default, verify what you can, and grant the minimum access the job requires. That is essentially the zero-trust model applied to a scraper’s egress path.
A short, non-sensitive experiment against public data is a defensible use. Production collection, credentials, personal data, private endpoints, and anything a customer depends on are not. If you want to be precise about where the line sits, note that a proxy controls one thing only: which address the target sees. It does not make you anonymous, and hiding your real IP address is a much narrower goal than most people assume — cookies, account state, browser fingerprints, and request rhythm all identify a scraper independently of its IP.
If you run the test anyway, keep it boxed in:
- Use an isolated environment with no access to internal systems.
- Send no passwords, API keys, tokens, session cookies, or personal data.
- Leave TLS certificate validation on.
- Touch only endpoints you are authorized to access.
- Validate response content rather than trusting
200. - Diff a sample against a trusted direct connection.
- Assume the operator sees your metadata: timings, destinations, volumes.
- Keep scheduled or revenue-critical jobs off public proxies entirely.
When a Free Proxy Is Genuinely Enough
A handful of situations justify one: a student learning how HTTP proxying works, a one-off check of how a page renders from another country, a proof of concept where the answer is “does this even parse.” The common thread is that a wrong answer costs you five minutes, not a dataset.
The moment the output feeds a decision — pricing, inventory, compliance monitoring, a customer-facing dashboard — the calculus flips. A single corrupted week of data usually costs more than a year of paid egress.
Better Alternatives to Free Proxies

The cheapest reliable path is usually not a proxy at all. Work through these in order.
Use an Official API or Licensed Dataset
When an API exists, it beats a proxy on every axis that matters: structured responses, documented limits, versioning, and a contract you can point at when something breaks. You also stop maintaining selectors against a site redesign you did not see coming.
The fee is real, but price it against the engineering time a fragile scraper consumes. A web scraping API that handles rendering, retries, and IP rotation for you can land in the same range as a self-built stack, without the on-call burden. Feeds, data exports, partner integrations, and licensed datasets often satisfy the underlying business need with less risk still.
Scrape Directly at a Responsible Rate
Plenty of projects never needed a proxy. If you are collecting a modest volume of public pages, direct requests with sane pacing are simpler, faster, and fully under your control.
Optimize before you rotate. Deduplicate your URL queue, pull incrementally instead of re-downloading unchanged pages, keep timestamps, cap concurrency, and add exponential backoff. The discipline is the same one described in API rate limiting — the target’s capacity is the constraint, whether you reach it over an API or over HTTP. For small, manually reviewed jobs, an instant data scraper Chrome extension may be all the tooling you need.
Evaluate Reputable Paid Providers
A commercial provider buys you accountability: an authenticated endpoint, a named company, a support channel, a documented retention policy, and capacity you can actually measure. It does not buy you a guarantee, which is why the questions below still apply.
Ask any candidate directly:
- What traffic and connection data do you log, and for how long?
- Is the client-to-proxy connection encrypted end to end?
- How are the IP addresses obtained?
- Have device owners given informed, revocable consent?
- How does someone opt their device out of the network?
- How are abuse complaints investigated, and by whom?
- What uptime, latency, and concurrency commitments are in the contract?
- Does the acceptable-use policy permit your specific activity?
Vague answers to the first two are a reason to keep looking. If you are benchmarking vendors, note that even the free tiers of commercial products deserve the same scrutiny. Oxylabs’ free proxy offering, for example, sits in a different category from a scraped list only if the retention and sourcing terms actually hold up when you ask.
Consider Datacenter Proxies
Datacenter proxies run on hosting-provider addresses. They are fast, comparatively cheap, and easy to reason about. The tradeoff is visibility: targets can identify datacenter ranges from published ASN data and throttle them on sight.
For sites that tolerate automation and do not blanket-block hosting IPs, datacenter addresses are often the best balance of cost, transparency, and speed. The full breakdown of how the two pools differ is in datacenter proxies versus residential proxies.
Approach Residential Proxies Carefully
Residential proxies use consumer connection addresses, which clear more IP-type filters but raise a sourcing question you have to answer before you buy.
Much of the residential pool is built from software running on ordinary people’s devices — sometimes with clear consent and compensation, sometimes with neither. Before you send traffic through it, establish whether participants knowingly agreed, understand that their bandwidth is resold, can leave easily, and were told what the traffic is. What residential proxies actually are is worth reading before that conversation, and mobile versus residential pools explains why carrier-grade addresses behave differently under blocking pressure.
A household IP is not ethical cover. If a provider cannot explain where its addresses come from in plain language, that is your answer.
Let an Extraction Agent Handle the Rendering
For sites that ship JavaScript-heavy interfaces, the rotating-IP problem is often downstream of the real problem: the page has to run before there is anything to parse. Managed extraction agents bundle rendering, retries, and egress management into one endpoint. TinyFish AI’s approach is one example of that category, and it is a fair comparison point when you are pricing a self-built stack.
How to Evaluate a Proxy Before You Rely on It
Test it against your own targets, over several days, with real request shapes. A proxy that loads example.com instantly has told you almost nothing.
| Evaluation area | What to measure or verify |
|---|---|
| Ownership | Identifiable operator, company details, policies, abuse contact |
| Security | Supported protocols, TLS handling, authentication, certificate validation |
| Privacy | Logging categories, retention period, sharing, deletion options |
| IP sourcing | How addresses are obtained; whether device owners consented |
| Availability | Connection success rate measured across several days |
| Latency | Median and 95th-percentile response times, not the average |
| Data integrity | Body hash and DOM diff against a trusted direct connection |
| Block rate | Frequency of 403, 429, CAPTCHAs, and challenge pages |
| Location | Observed country and region matching what was advertised |
| Support | Incident reporting, troubleshooting, abuse handling |
Run the tests against endpoints you are authorized to access, keep credentials and personal data out of the sample, and record results over time. One clean afternoon proves nothing about next month.
Language choice shapes how much of this you implement by hand. This comparison of Ruby vs. Python for web scraping covers the ecosystem side, but response validation and request discipline are on you in any language.
Legal and Ethical Considerations
A proxy changes the network path. It does not change whether the collection itself is lawful or permitted — those questions are answered by the data, the access method, the contract, and the jurisdiction.
Before you start, work through:
- Is the information public, or does it require an account?
- Does your scraper circumvent a technical access control?
- What do the terms of service and published policies say?
- Do copyright, database rights, or contracts restrict reuse?
- What privacy and personal-data rules apply?
- How much automated traffic will you send?
- Will you republish, sell, profile, or combine the results?
- Which jurisdictions are involved for the site, your organization, and the people in the data?
A ruling about public web data in one country is not a global license. For the broader picture, see whether web scraping is legal, and if the work involves personal data, authenticated accounts, or commercial redistribution, get it reviewed by qualified counsel rather than a blog post — including the specific status of scraping APIs, which is not automatically cleaner than scraping the page.
Robots.txt Is a Crawler Preference, Not Authentication
A robots.txt file states how a site would like automated crawlers to behave. Check it, along with the terms and API documentation, as part of responsible operation.
Technically, though, robots.txt is not an authentication mechanism and not an access-control system. It cannot stop a server from returning a resource, and treating it as a security boundary misunderstands what it is. The Robots Exclusion Protocol specification is explicit that these rules are not a form of access authorization and are not a substitute for real content security measures.
That does not make the file irrelevant. Honoring it reduces pointless load, keeps you out of paths the site has flagged, and is simply good manners in a shared system. Its legal weight, meanwhile, depends on jurisdiction and facts — it is neither a blanket prohibition nor a blanket permission.
A Proxy Does Not Reduce Server Load
Routing 10,000 requests through 10 proxies still sends 10,000 requests to the target. The website does the same work; only the return address changed.
If impact is the concern, change the request pattern:
- Use an official API, export, feed, or licensed dataset where one exists.
- Set conservative rate and concurrency limits.
- Cache what can be reused, where the terms allow it.
- Collect only the pages and fields the project needs.
- Prefer incremental updates over full re-downloads.
- Cap retries and back off instead of hammering a failing endpoint.
- Monitor error rates and stop the job when the target starts returning persistent failures.
- Contact the site owner before high-volume or unusual collection.
The distinction between aggressive scraping and a small distributed denial-of-service attack is mostly intent plus volume. Proxies let you scale volume without adding capacity, which is exactly the property that turns a modest scraper into an unwelcome one. Treat the proxy as infrastructure, not as a way to make a heavy job invisible.
Frequently Asked Questions
Are free proxies illegal?
No. Using a proxy is not itself illegal anywhere we can point to. Legality attaches to what you collect and how — the data type, the access method, the site’s terms, and the jurisdiction. A proxy only changes the network path, so switching to a paid provider does not fix a collection practice that was already a problem.
Can a free proxy change the content I scrape?
Yes, and it happens at scale. The MADWeb 2024 study found 16,923 proxies manipulating content out of more than 640,000 tested. The defense is cheap: hash the response body, diff the DOM against a direct fetch, and assert that expected elements are present before you write a row.
Is a paid proxy automatically safer?
No. Paying buys accountability — a named company, a support channel, a retention policy you can read. It does not buy correctness. Ask the same sourcing, logging, and integrity questions you would ask of a free provider, and test the endpoint instead of trusting the marketing page.
When is a free proxy acceptable for scraping?
For narrow experiments where a wrong answer costs minutes: learning how proxying works, checking a page from another region, validating that a parser handles a template. Keep it isolated, send no credentials, leave TLS validation enabled, and never point a scheduled production job at a public list.
How do I tell whether a proxy tampered with a page?
Fetch the same URL directly and through the proxy within a short window, then compare the body hash and the parsed DOM. Differences in ads, canonical links, script tags, or prices are the signal. Logging that hash on every request also builds a baseline you can alert on later.
Do I even need a proxy for web scraping?
Often not. If you are collecting a modest volume of public pages at a polite rate, direct requests are simpler and fully observable. Add proxies when the target’s blocking is the actual bottleneck — not before you have deduplicated the queue, capped concurrency, and added backoff. Plenty of “proxy problems” are really rate problems.
Conclusion
Free proxies trade a small line item for a large set of unknowns: who runs the server, how long it keeps your metadata, whether the IP was burned before you got it, and whether the page it handed you is the page the site served.
Their worst failure is quiet. An outage is obvious and recoverable; a manipulated response that passes your status check is neither.
Build in this order. Try a direct, rate-limited collector. If that is not enough, use an official API or a licensed dataset. If you genuinely need rotation, pick a provider you can evaluate and keep monitoring, validate every response body, record the observed exit location, and stay inside the technical and legal limits that apply to your project. The goal was never a clean IP list. It was data you can defend.
You May Also Like
 Web Scraping
10 Best ScrapingBee Alternatives: Real Cost per 1,000 Pages
 Web Scraping
8 Best Web Scraping APIs for E-commerce Sites
 Web Scraping
Instant Data Scraper: Features, How to Use It, and Honest Limitations
 Web Scraping
Are Web Scraping and Web Crawling the Same Thing?
 Web Scraping
Google Maps Scrapers: Guide for Local Business Data Extraction
 Web Development
REST API vs SOAP API: Differences, Pros & Cons, and Use Cases
 Data Security & Privacy
API Security Best Practices for Data Collection Platforms
 Web Development
What Is API Rate Limiting? (A Practical, Simple Guide for Safer, Faster APIs)
 VPN & Proxy
