


Most security teams don’t have a vulnerability problem as much as a prioritization problem. A single scan of a mid-sized network can return thousands of findings, and no team can fix them all at once. The list is also rarely sorted by real risk. The goal is to fix the right things first.
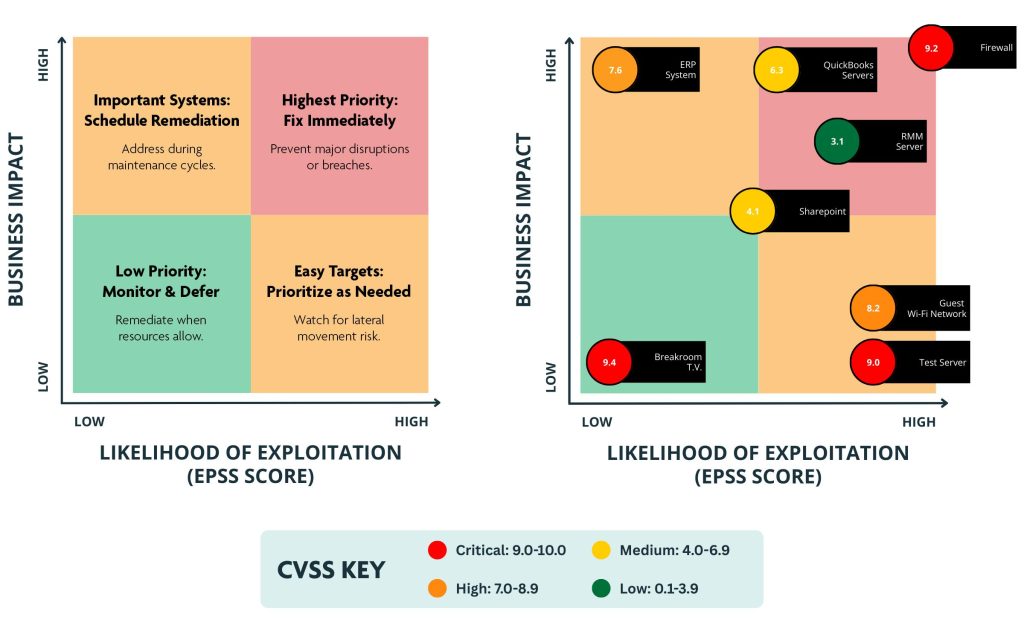
Prioritize vulnerabilities by combining four signals: how severe the flaw is, whether attackers are using it, how likely it is to be used, and how exposed and important the affected system is. A single score, such as CVSS alone, can’t tell you what to fix first.
This guide covers practical strategies for building that kind of prioritization. It draws on public guidance from CISA, NIST, and FIRST, plus secondary commentary where noted. We haven’t benchmarked these approaches in a live environment, so treat the timelines and tiers as starting points.
Why Severity Scores Alone Fall Short
Severity scores are useful, but they answer a narrow question. The Common Vulnerability Scoring System (CVSS) describes how bad a flaw could be if someone used it. It doesn’t say whether anyone is using it, whether the affected system is reachable from the internet, or whether losing that system would hurt your business.
The National Vulnerability Database adds CVSS scores, weakness categories, and product matches to published vulnerabilities. It doesn’t test vulnerabilities itself. Its data tells you how severe a flaw is, not whether it’s being exploited right now. CloudSEK’s knowledge base makes the same point. It also describes NIST’s 2026 move to fully analyze only its highest-priority vulnerabilities, which means some newer CVEs may arrive without a NIST-assigned score.
Here’s a simple example (hypothetical). A flaw rated 9.8 sits on an isolated test server with no internet access. A flaw rated 7.5 sits on the VPN appliance your remote staff uses every single day, and attackers are already exploiting it. A severity-only list puts the test server first. A risk-based list puts the VPN appliance first.
Strategy 1: Build an Accurate Asset Inventory and Ownership Map
You can’t prioritize what you don’t know exists. Before you rank a single vulnerability, you need to know what systems you have, who owns each one, and what each one does.
For each asset, record at least these details:
- Owner. The person or team who can approve changes.
- Business function. What the system supports, such as billing, payroll, or customer support.
- Internet exposure. Whether the system can be reached from outside your network.
- Data sensitivity. What information it stores or processes.
- Criticality. What happens if the system goes down or is compromised.
An inventory doesn’t need to be perfect to be useful. Start with your most important systems and expand over time. The biggest gains usually come from knowing about internet-facing systems and identity systems first.
Coverage matters too. Cogent’s vulnerability management guidance notes that coverage gaps are risk gaps. If part of your environment never gets scanned, its vulnerabilities pile up unseen.
Strategy 2: Layer Exploitation Signals on Top of Severity
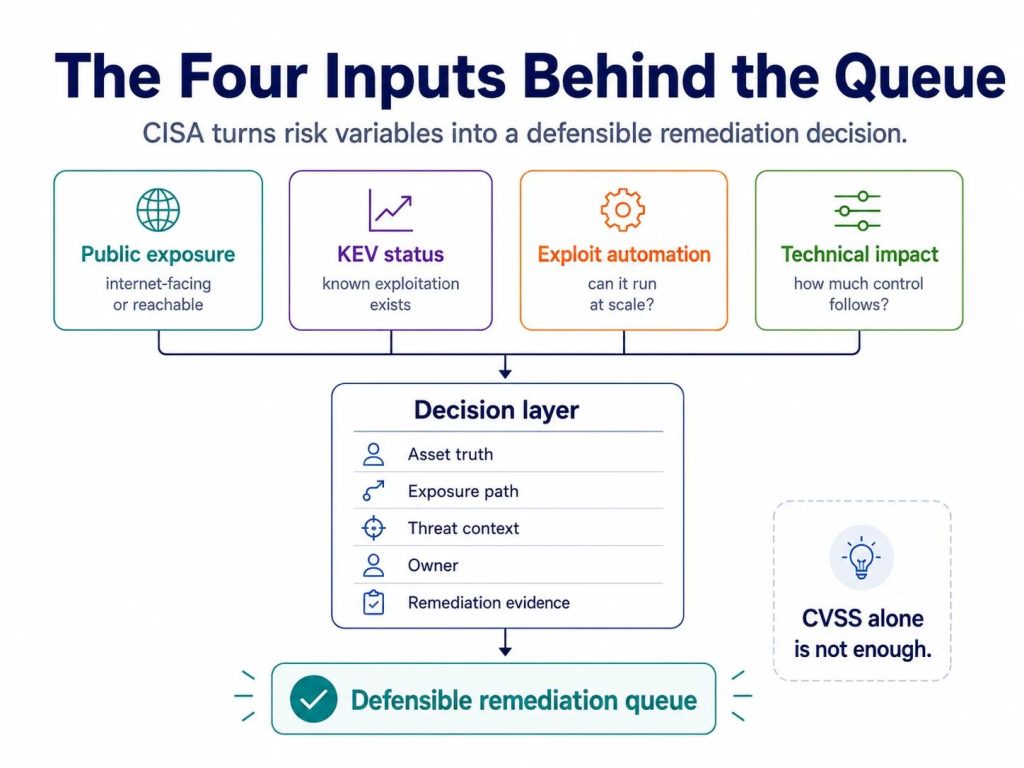
The most effective change most teams can make is adding exploitation data to severity data. Three sources do different jobs, and each one has limits.
| Signal | Question it answers | Limits |
|---|---|---|
| CVSS (via NVD) | How bad could it be? | Describes potential impact, not real-world use |
| EPSS | How likely is exploitation in the next 30 days? | A model estimate, not a guarantee, and it describes the flaw in general, not your environment |
| KEV | Is it being exploited right now? | A historical record, so it can lag behind new attacks |
| Asset context | What happens if it’s exploited here? | Depends on how complete and accurate your inventory is |
EPSS is a model maintained by FIRST. According to Bitsight’s glossary, EPSS gives each CVE a score from 0 to 1 that estimates the probability of exploitation within the next 30 days. The model considers factors such as whether a public exploit exists and how complex exploitation is. Use it to rank the flaws that deserve attention sooner, not as a promise about what will happen.
KEV is the catalog of vulnerabilities CISA has evidence are being actively exploited. Under Binding Operational Directive 22-01, federal civilian agencies must fix KEV entries by set due dates, and CISA encourages all organizations to prioritize them. If a finding appears on KEV, it should jump the queue, regardless of its severity score.
Combine the signals in a simple way. A high CVSS score with no exploitation evidence is a planning item. A high CVSS score with a KEV listing on an internet-facing system is an emergency.
Strategy 3: Use a Decision Framework With Clear Tiers
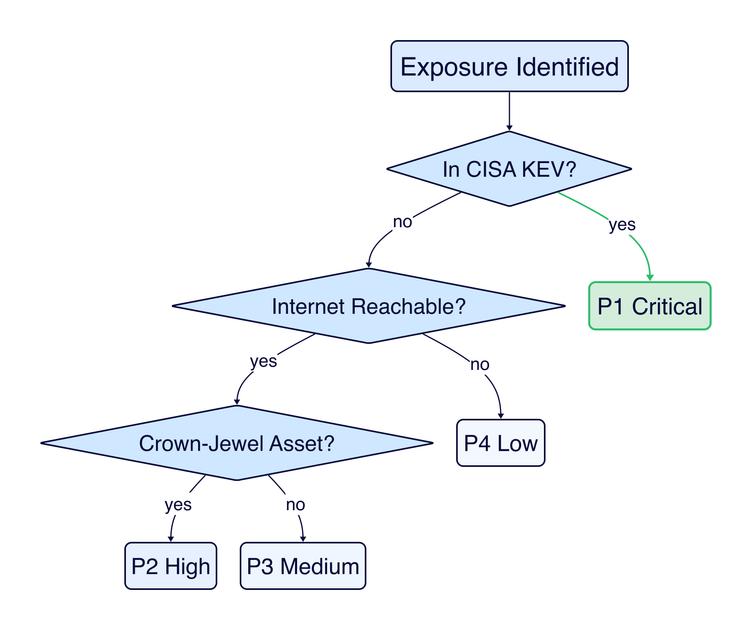
Ranking findings by a single number creates arguments. A decision framework creates consistency. It answers the question “what do we do next?” instead of “how bad is this?”
CISA’s Stakeholder-Specific Vulnerability Categorization (SSVC) is a free, public model built around five decision points: exploitation status, technical impact, automatability, mission prevalence, and public well-being impact. Each vulnerability moves through a decision tree that ends in one of four outcomes: Track, Track, Attend, or Act. Track means standard monitoring. Track means monitor closely and fit the fix into the next patch cycle. Attend means urgent work in the current cycle. Act means immediate action.
You don’t have to implement the full SSVC tree to get the benefit. Many teams use a simplified tier model based on the same ideas. Here’s a starting point that you can adjust:
| Tier | Typical criteria | Example target | Typical action |
|---|---|---|---|
| Tier 0: Emergency | KEV-listed or active exploitation, on an internet-facing or critical asset | Days | Emergency change, escalation to leadership |
| Tier 1: Urgent | High severity with a known exploit or high EPSS, or a business-critical asset | Within 2 weeks | Next urgent change window |
| Tier 2: Planned | High severity, no known exploit, internal asset | Within 30 days | Regular patch cycle |
| Tier 3: Routine | Medium or low severity, low exposure | Next quarterly cycle | Batch updates |
These timelines are examples. Set your own based on staffing, change windows, and risk tolerance. What matters most is that every tier has a defined target, an owner, and a visible status.
Strategy 4: Factor In Exposure and Business Impact
Some systems matter more than their scores suggest. Attackers rarely stop at one compromised machine. They look for a path to something valuable. That makes certain asset types high priority even when their individual flaws look moderate.
Give extra weight to:
- Internet-facing systems, such as web servers, VPN appliances, and remote access gateways.
- Identity systems, such as directory services and single sign-on, because control of these can unlock everything else.
- Backup systems, because attackers often target backups before a ransomware attack. Our guide on protecting backup data from ransomware covers this in more detail.
- Systems holding sensitive data, such as payroll, customer records, or health information.
- Systems that support essential operations, where downtime itself is costly.
A flaw on a backup server can matter more than a higher-scored flaw on a system with no sensitive data and no network path to anything important. Write this logic into your process so that decisions don’t depend on who argues the loudest.
Strategy 5: Use Compensating Controls When You Can’t Patch Right Away
Sometimes the right fix isn’t available yet. The vendor hasn’t released a patch, the system can’t be taken offline during business hours, or the application depends on an older component that breaks after updates. In those cases, compensating controls reduce risk until you can fix the flaw.
Common compensating controls include:
- Restricting network access so only required systems can reach the vulnerable service.
- Moving the system into a segment with tighter rules.
- Requiring multi-factor authentication for access to the system.
- Adding web application firewall rules that block known attack patterns.
- Disabling unused services and features.
- Increasing monitoring and alerting around the system.
Document every compensating control, the risk it reduces, and the date you’ll review it. A compensating control is a bridge, not a destination. Without an expiry date, temporary workarounds become permanent. For operational technology and other specialized equipment, check the vendor’s guidance first, because some standard controls can disrupt the device.
Strategy 6: Separate Urgent Work From Routine Maintenance
Teams often fall into a trap. They fix the easiest findings first, because closing tickets feels productive. The result is a long list of low-risk items completed while high-risk findings wait.
Split your work into two lanes:
- Urgent lane. Tier 0 and Tier 1 findings get dedicated attention, clear owners, and change windows set aside for them. This lane should move quickly and have pre-approved emergency change paths.
- Routine lane. Tier 2 and Tier 3 findings go through regular maintenance. Here, automation pays off. Automated patching for low-risk systems, scheduled monthly, can clear large volumes of routine findings without pulling attention from urgent work.
Our guide to an automated patch management process explains how to set up the routine lane. Automate where the risk is low and testing is predictable. Keep manual review for systems where a patch could break something important.
Strategy 7: Plan Changes Around Testing and Dependencies
Urgent doesn’t mean careless. A patch that fixes one vulnerability but breaks a payroll run creates a new problem. Good prioritization includes planning for testing, dependencies, and rollback.
Before you push an urgent change:
- Check dependencies. Know which other systems rely on the one you’re patching.
- Test in staging where possible, even if the test is quick.
- Prepare a rollback plan that someone has actually tried, not just written down.
- Schedule the change in a window the system owner has approved.
- Notify the affected teams before the change, with clear instructions for what to watch for.
For Tier 0 findings, define in advance how an emergency change gets approved. Waiting for a full change board meeting during an active exploit defeats the purpose of prioritization. Our vulnerability management policy example shows how a written policy can set these approval paths before an emergency happens.
Strategy 8: Track Risk Acceptance With Expiry Dates
Some findings won’t be fixed. The cost is too high, the system is being retired, or the risk is low enough that the business accepts it. That’s a legitimate decision, but it needs discipline.
Every accepted risk should include:
- A named owner who has the authority to accept the risk.
- A written reason and the compensating controls in place.
- An expiry date, usually no more than one year out, when the decision gets reviewed.
- A plan for what happens if the risk increases, such as a new exploit appearing.
Review accepted risks on a schedule. A common failure is the “permanent exception” that nobody remembers. Track the number of open exceptions, their age, and how many have passed their review dates. A growing exception list is often a sign that your remediation process isn’t keeping pace with your findings.
Strategy 9: Measure Outcomes, Not Just Activity
Scan counts and ticket volume measure effort. They don’t show whether risk is going down. Choose metrics that reflect real progress.
Useful outcome metrics include:
- Mean time to remediate (MTTR) by severity and tier. Cogent describes MTTR by severity as the most important operational metric, because a blended average can hide a serious backlog of critical issues.
- Number of open KEV-listed findings. Ideally, this should be close to zero at all times.
- Percentage of high-risk findings past their target. This shows whether your tiers are being respected.
- Number of open risk exceptions and how many are overdue for review.
- Reopen rate. How often a “fixed” finding comes back.
Targets for these metrics depend on your environment. Track trends over time rather than fixating on a single number. A steady improvement in MTTR for Tier 1 findings tells you more than one good week.
Strategy 10: Verify Fixes and Watch for Reopens
A closed ticket is not the same as a fixed vulnerability. Verify each high-priority fix with a rescan or a direct check of the affected version or setting. Patches sometimes fail silently. Configuration changes sometimes get reverted by an automated process. Software updates sometimes reintroduce old flaws.
Build verification into the workflow:
- Rescan after every Tier 0 and Tier 1 change.
- Check the installed version directly for critical systems.
- Watch for reopened findings in the following weeks.
- Keep evidence of verification with the ticket, so future audits don’t require reconstruction.
A Worked Example (Hypothetical)
Here’s how five findings from one scan might be prioritized for a mid-sized company. The findings are illustrative, not from a real environment.
| Finding | CVSS | KEV listed | Exploit likelihood | Exposure and impact | Tier | Action |
|---|---|---|---|---|---|---|
| VPN appliance firmware flaw | 9.8 | Yes | High | Internet-facing, remote access | Tier 0 | Emergency change within days, leadership notified |
| Missing patch on domain controller | 8.8 | No | Moderate | Internal, identity system | Tier 1 | Urgent change within two weeks |
| Public web server library flaw | 7.5 | No | High | Internet-facing | Tier 1 | Urgent change, add WAF rule as a stopgap |
| Developer laptop app vulnerability | 9.1 | No | Low | Internal, limited data | Tier 2 | Regular patch cycle within 30 days |
| Outdated library on isolated test server | 5.3 | No | Low | No network path to production | Tier 3 | Routine batch update |
The table shows something useful. The developer laptop has the second-highest CVSS score in the list, but it lands in Tier 2 because its exploit likelihood is low and its exposure is limited. The VPN appliance, which scores slightly higher than the domain controller, moves to the top because it’s on KEV and internet-facing. The domain controller stays high because it’s an identity system, even without a KEV listing.
Common Mistakes to Avoid
- Sorting only by CVSS score. This ignores exploitation and exposure.
- Treating EPSS as certainty. A low score doesn’t mean a flaw is safe, and a high score doesn’t guarantee an attack.
- Clearing easy tickets first. This creates a healthy-looking dashboard while urgent risks sit open.
- Forgetting about asset coverage. Unscanned systems carry risk you can’t see.
- Accepting risk without expiry dates. Temporary exceptions quietly become permanent.
- Skipping verification. Closed tickets don’t always mean fixed systems.
- Ignoring dependencies. A fast fix that breaks a critical process creates a second incident.
- Using one tier model for every team. A hospital and a software company have different mission priorities. Tailor your criteria.
Putting It Together: A Simple Operating Rhythm
Prioritization works best as a routine, not a one-time project. A practical rhythm looks like this:
- Daily: Check for new KEV entries that affect your assets. Escalate any matches to Tier 0.
- Weekly: Review new findings, assign owners, and confirm tier placement for new Tier 0 and Tier 1 items.
- Monthly: Review MTTR, overdue high-risk items, open exceptions, and reopened findings. Adjust routine patching schedules.
- Quarterly: Review your tiers, your asset inventory, and your policy. Update decision criteria if your environment or threat landscape has changed.
For a broader view of how scanning fits into this process, our guide to what vulnerability scanning is and how it works explains the inputs. If you’re comparing the roles of scanning, testing, and management, see our explainer on vulnerability scanning and penetration testing. Organizations that want to widen the lens should also read about vulnerability management and attack surface management. For a practical starting checklist, our network security audit checklist helps you confirm your coverage before you tune your priorities.
Conclusion
Effective prioritization isn’t about finding the perfect score. It’s about combining the right signals and turning them into clear decisions. Start with an accurate inventory, add exploitation data to severity, and use tiers with defined targets. Factor in exposure and business impact, and use compensating controls when you can’t patch right away. Separate urgent work from routine maintenance, track exceptions with expiry dates, and measure outcomes instead of activity.
If you do only one thing this month, check whether any open findings on your internet-facing systems appear on the KEV catalog. Those are the ones that need your attention today.
You May Also Like
 Data Security & Privacy
Tokenization vs Encryption: Key Differences and Best Practices
 Data Security & Privacy
How Encryption Works: A Practical Guide to Data Encryption Best Practices
 Cybersecurity
Why Strong Passwords Are Important?
 Data Security & Privacy
Endpoint Security vs Antivirus: Key Differences for Better Protection
 Network Security
What is Penetration Testing and Why Is It Crucial for Your Cybersecurity Strategy?
 Network Security
11 Best Free Penetration Testing Tools: Your Complete Guide for 2027
 Cybersecurity
What Is Endpoint Management? A Practical Guide for Modern Teams
 Data Security & Privacy
The Importance of Vulnerability Management and Attack Surface Management
 Web Development
